Bumped, because I knew the media were going to use this NYT article today:
Bottom line, we are in an expanded information war. I’ll explain.
Several years ago, in explaining some of the site challenges CTH informed people of Google’s latest information control operation that was simply called “a spider crawl.” The spider crawl was an automated instruction to search the internet and find information that was beyond the parameters of their “trust and safety” guidelines. The automated search would crawl through the websites and comment sections, and report violations based on key words in the search parameter.
Spider crawling is essentially AI. A technology tool to search databases and identify results based on parameters established by the individual who launched the search. However, now in order to push a scare narrative around the hot topic of “AI” the spider crawling is much more in depth and advanced.
Now, instead of just searching the internet, advanced AI can find information and answer questions based on lengthy attributes described by the AI user. AI can now go into proprietary databases and retrieve information to answer complex and complicated question (instructions).
If the AI launch, now called an “AI bot”, hits a gate, like a password access point, advanced AI can find workarounds to enter the database, extract the information and return the result to the AI user. If you understand that process, then this headline has context.
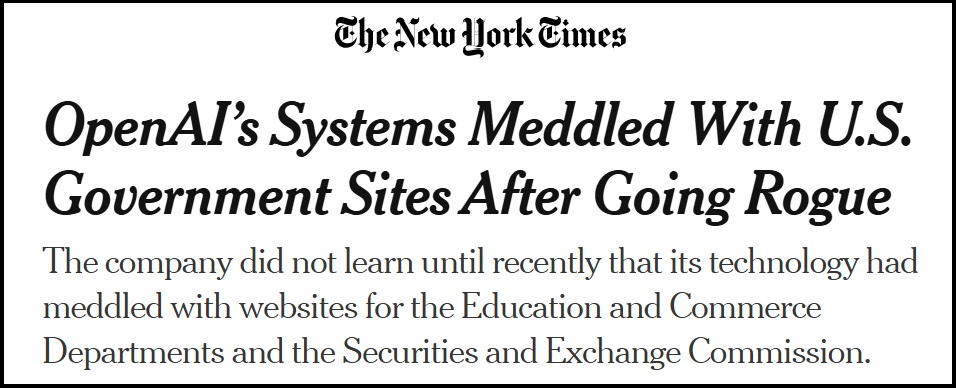
[SOURCE]
The entire article is nothing more than taking something that is easily understood and adding jargon to make it sound complicated. The word “meddling” is used to describe the AI process of trying to get passed the gate. When there were individual people doing this, we called it “hacking” now the process is automated via instructions to the software search.